SXD-N430UW Edge Analytics Appliance (48 TOPS)
Specification · SXD-N430UW (1U rack-mount) · 48 TOPS@INT8 / 12 TOPS@INT16 / 384 GFLOPS FP32
The SXD-N430UW Edge Analytics Appliance is a 48 TOPS edge AI analytics device, rated to support 128 channels of real-time video input (1080P, one algorithm per…
No. sxd-n430uw-edge-analytics-appliance-48-tops · 2026-11-20
Overview
Product Overview
The SXD-N430UW Edge Analytics Appliance is a 48 TOPS edge AI analytics device, nominally supporting 128 channels of real-time video access (1080P, one algorithm per channel, frame sampling every 2 seconds). The actual number of supported channels varies with camera resolution, frame sampling interval, and the number of algorithms per channel, and should not be interpreted as a fixed channel count. For selection guidance, see "Compute and Channel Capacity Basis" below.
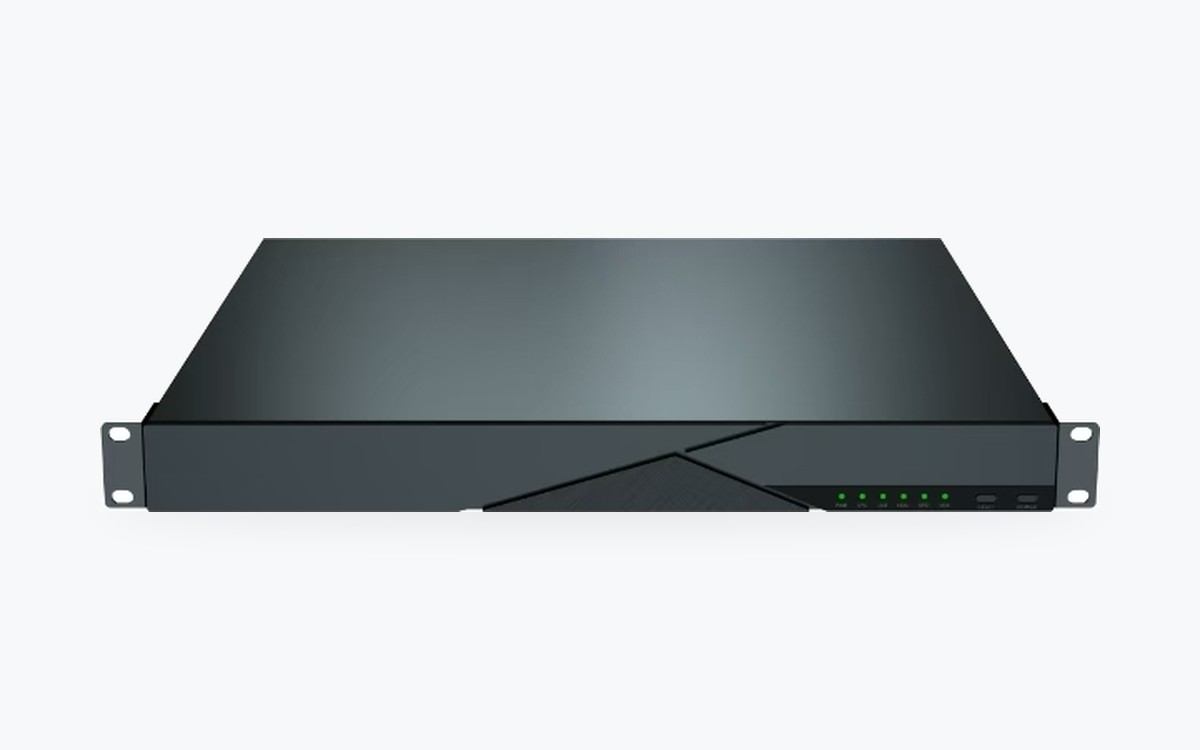
The SXD-N430UW is the flagship appliance of the N430 series: three 24-core processors, 48 TOPS@INT8 compute, supporting 128 channels of 1080P decoding and 24 channels of encoding, designed for large campuses and scenarios with multiple concurrent algorithms. The four-network-port design facilitates multi-subnet access, making it suitable for deployment environments where the video private network and office network are separated.
Compute and Channel Capacity Basis
The nominal "128 channels" refers to the number of real-time video access channels, with the baseline specification of 1080P, 25fps, one algorithm bound per channel, and frame sampling every 2 seconds. The actual number of supported channels is not a fixed value and varies with three variables:
| Variable | Change | Impact on Compute |
|---|---|---|
| Camera resolution | 2 MP → 4 MP | Per-channel decoding and inference load increases by approximately 50%–100%, and the supported channel count decreases accordingly |
| Frame sampling interval | 2 seconds → 1 second | Frames processed per second doubles, and the supported channel count is approximately halved |
| Algorithms per channel | 1 → 2 | Inference count doubles, and the supported channel count is approximately halved |
Selection recommendation: First calculate based on "resolution × frame sampling frequency × algorithms per channel," then allow a 30% margin. 2 MP + 2-second frame sampling + single algorithm corresponds to the nominal channel count; when switching to 4 MP or 1-second frame sampling, estimate at 50%–60% of the nominal channel count. 48 TOPS is the INT8 peak compute, and the actual usable compute is affected by the algorithm model and concurrency strategy.
Dataflow Architecture and Effective Compute
Nominal compute is only an upper limit; what really determines how many channels can be supported is chip utilization. This appliance is equipped with a reconfigurable dataflow AI chip that compiles the entire algorithm model into a data pipeline, connecting operators directly into a hardware path. Computation is completed as data flows through, without repeated instruction fetching and intermediate result movement.
| Comparison Item | Instruction Set Architecture (common GPU/NPU) | Dataflow Architecture (this appliance) |
|---|---|---|
| Computation method | Executes operators one by one, with intermediate results repeatedly read from and written to memory | Operators are compiled into a pipeline; computation is completed as data flows through |
| Chip utilization (public industry comparison) | 10%–30% | 65%–95% |
| Effective compute converted from 8 TOPS | Approximately 0.8–2.4 TOPS | Approximately 5.2–7.6 TOPS |
| Supported channels at equivalent compute | Baseline | Approximately 2–3 times based on median utilization |
| Algorithm deployment | Depends on framework adaptation and manual tuning | In-house compiler; TensorFlow / PyTorch / ONNX models are automatically compiled end-to-end and deployed |
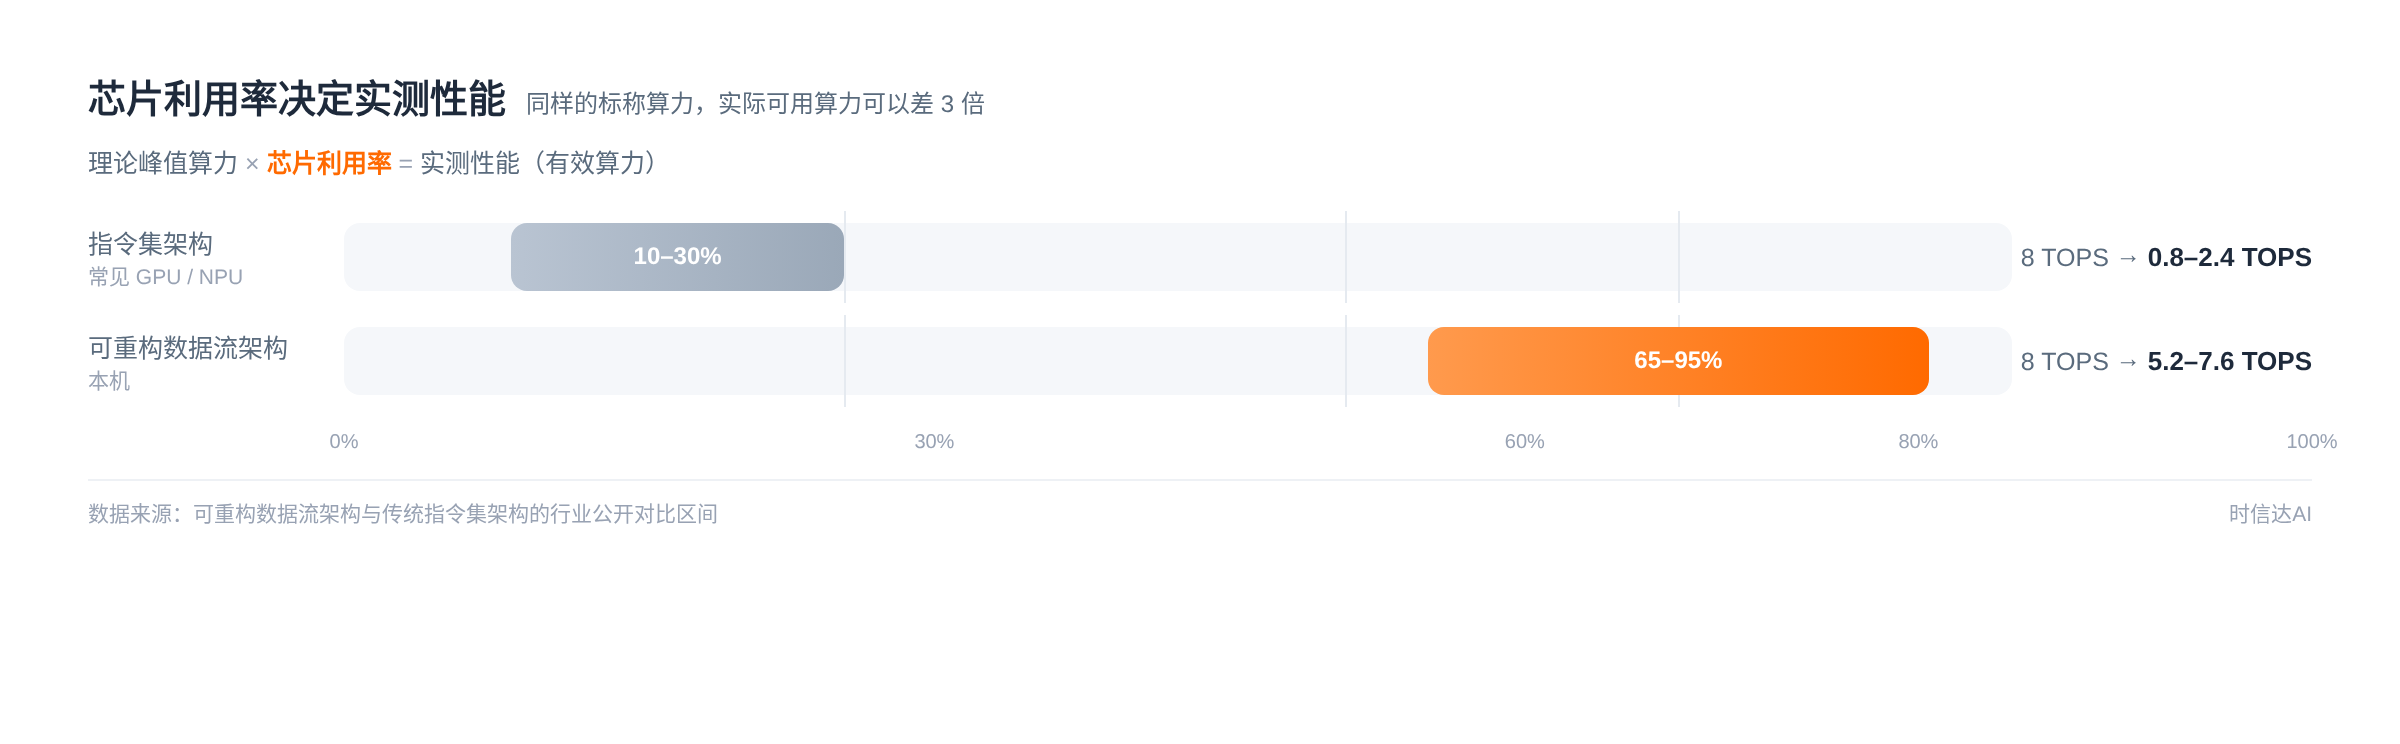
Effective compute = nominal peak × chip utilization. Taking 8 TOPS as an example: the instruction set approach provides approximately 0.8–2.4 TOPS of actually usable compute, while the dataflow approach provides approximately 5.2–7.6 TOPS — this is also why devices with the same nominal compute can differ greatly in the actual number of cameras they can support.
For real-world deployment scenarios, this means three things:
- More economical for existing system upgrades: One device replaces two to three previous devices, with rack space and power consumption reduced accordingly
- Reconfigurable algorithms: Changing algorithms does not require changing hardware; simply compile and deploy, avoiding the situation where "an algorithm upgrade requires replacing the box"
- Compute can run consistently at full capacity: During concurrent decoding and inference of multiple video channels, the pipeline can still maintain high utilization, avoiding the "high peak, low measured" problem
Note: The utilization values in the table are publicly available industry architecture comparison ranges; measured values for specific models will vary with operator structure, input resolution, and batching strategy. The nominal channel count on this page is given based on the specification of 1080P, one algorithm per channel, and frame sampling every 2 seconds.
Algorithm Capabilities (Categorized by Scenario)
The algorithms compatible with the device are divided into 6 major categories by scenario, covering 460+ sub-scenarios; which specific algorithms are enabled is configured per project and subject to the delivery list.
| Scenario Category | Representative Algorithms | Typical Locations |
|---|---|---|
| Personnel behavior and on-duty status | Area intrusion, line crossing, personnel lingering, loitering, climbing/fence crossing, fall detection, on-duty status monitoring, work procedure deviation, helmet/reflective vest/workwear/mask/glove wearing detection | Plant perimeter, duty room, work area |
| Safety risks and fire protection | Fire and smoke, open flame, smoke, fire lane obstruction, dangerous area intrusion, passage blockage, gas leakage, electrostatic discharge | Warehouse, power distribution room, kitchen, hazardous chemicals area |
| Vehicles and traffic | License plate recognition, illegal parking, wrong-direction driving, traffic flow statistics, non-motor vehicle intrusion, engineering vehicle recognition, height restriction | School gate, campus entrance/exit, roads |
| Objects and facilities | Material stacking, pallet recognition, empty shelf detection, equipment status, meter reading, conveyor anomaly | Workshop, warehouse, power distribution room |
| Environment and order | Garbage overflow, water accumulation, dust, road occupation, disorderly stacking | Plant roads, garbage room, construction area |
| Food and kitchen | Kitchen attire, rodent infestation, sample retention testing, tableware disinfection, cold chain temperature | School/enterprise cafeterias |
Note: Algorithm names are handled in accordance with external communication standards; algorithms involving human images must be used within the authorized scope. The table lists representative algorithms; the complete list is provided with the project.
Algorithm Training and Customization (Optional)
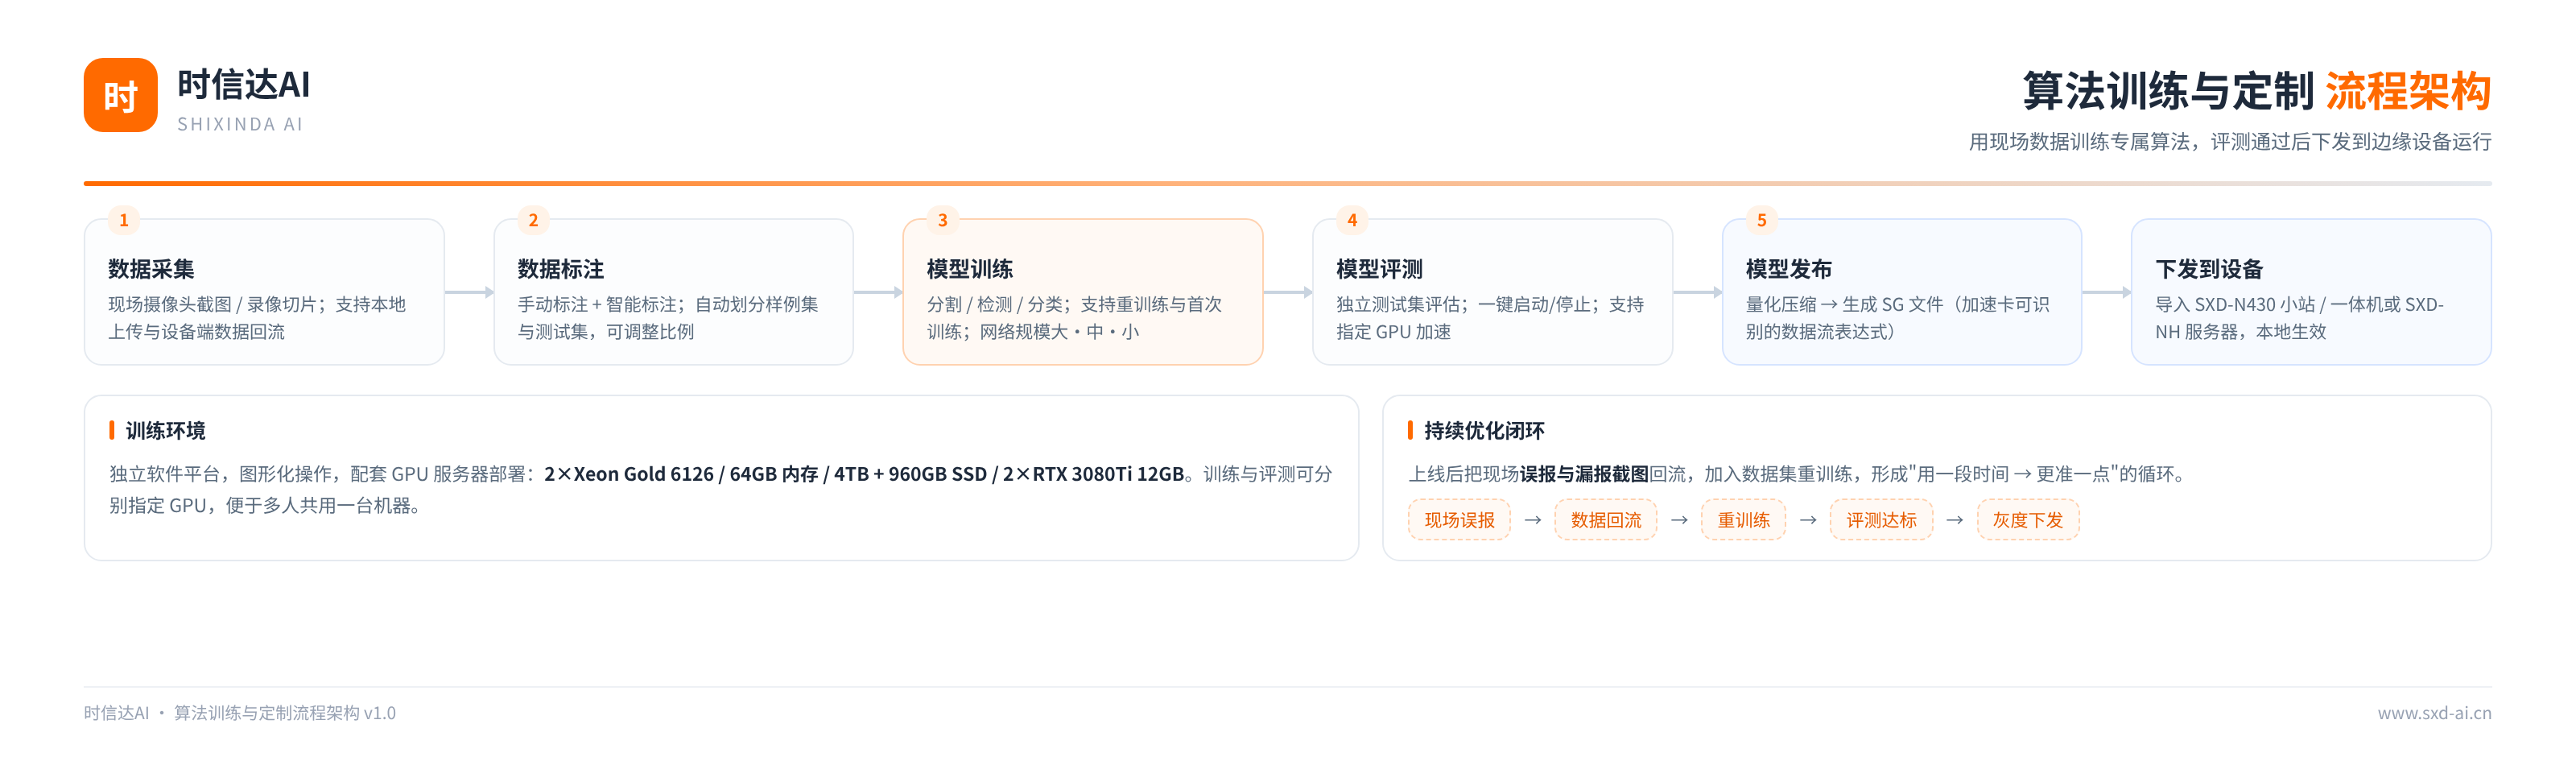
If general algorithms cannot cover on-site scenarios, the "AI Algorithm Training Platform" can be provided to train dedicated models using on-site data. After training is completed, quantization generates an SG file, which is deployed to the inference acceleration card on this appliance for execution. The platform features a graphical interface and completes the process in four steps: data annotation → model training → model evaluation → model release.
| Stage | Capability | Description |
|---|---|---|
| Data annotation | Manual annotation + intelligent annotation | Data can be uploaded locally,回流 from the site, or selected from platform datasets; sample sets and test sets are automatically partitioned |
| Model training | Segmentation / detection / classification | Supports retraining of existing models and first-time training on the model library; customizable images per batch and network scale (large/medium/small) |
| Model evaluation | Specified model + one-click evaluation | Evaluates performance using an independent test set; supports specified GPU acceleration |
| Model release | Quantization + SG file generation | Converts to a dataflow expression recognizable by the acceleration card and deploys to the edge device for execution |
The training platform is standalone software and requires a GPU server (reference configuration: 2×Xeon Gold 6126 / 64GB / 2×RTX 3080Ti), configured per project. Training results depend on sample quality and scenario coverage; it is recommended to validate with a small batch of data before large-scale collection.
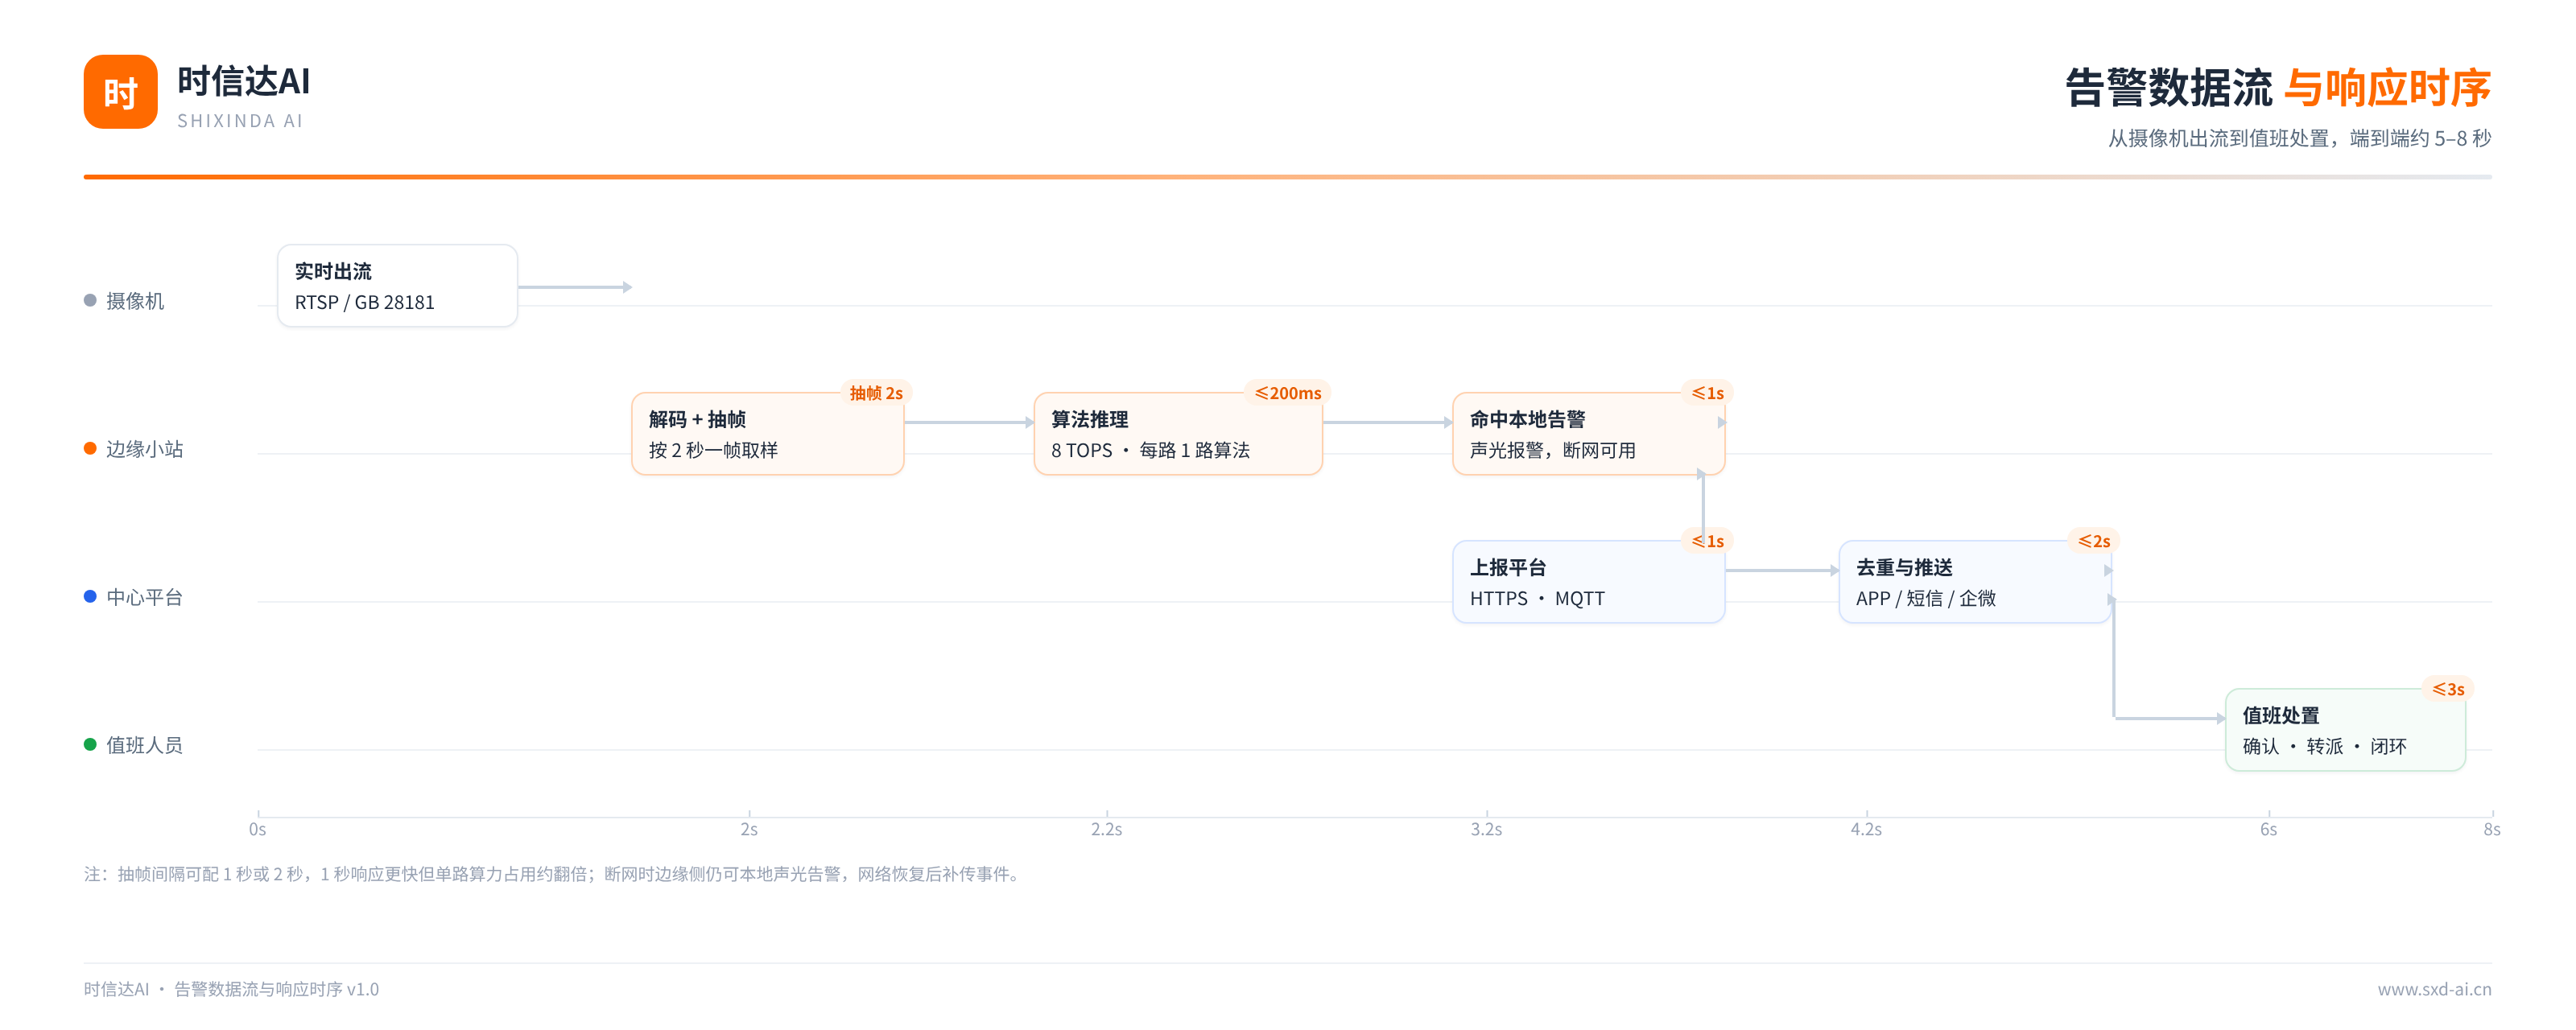
Alarm Dataflow
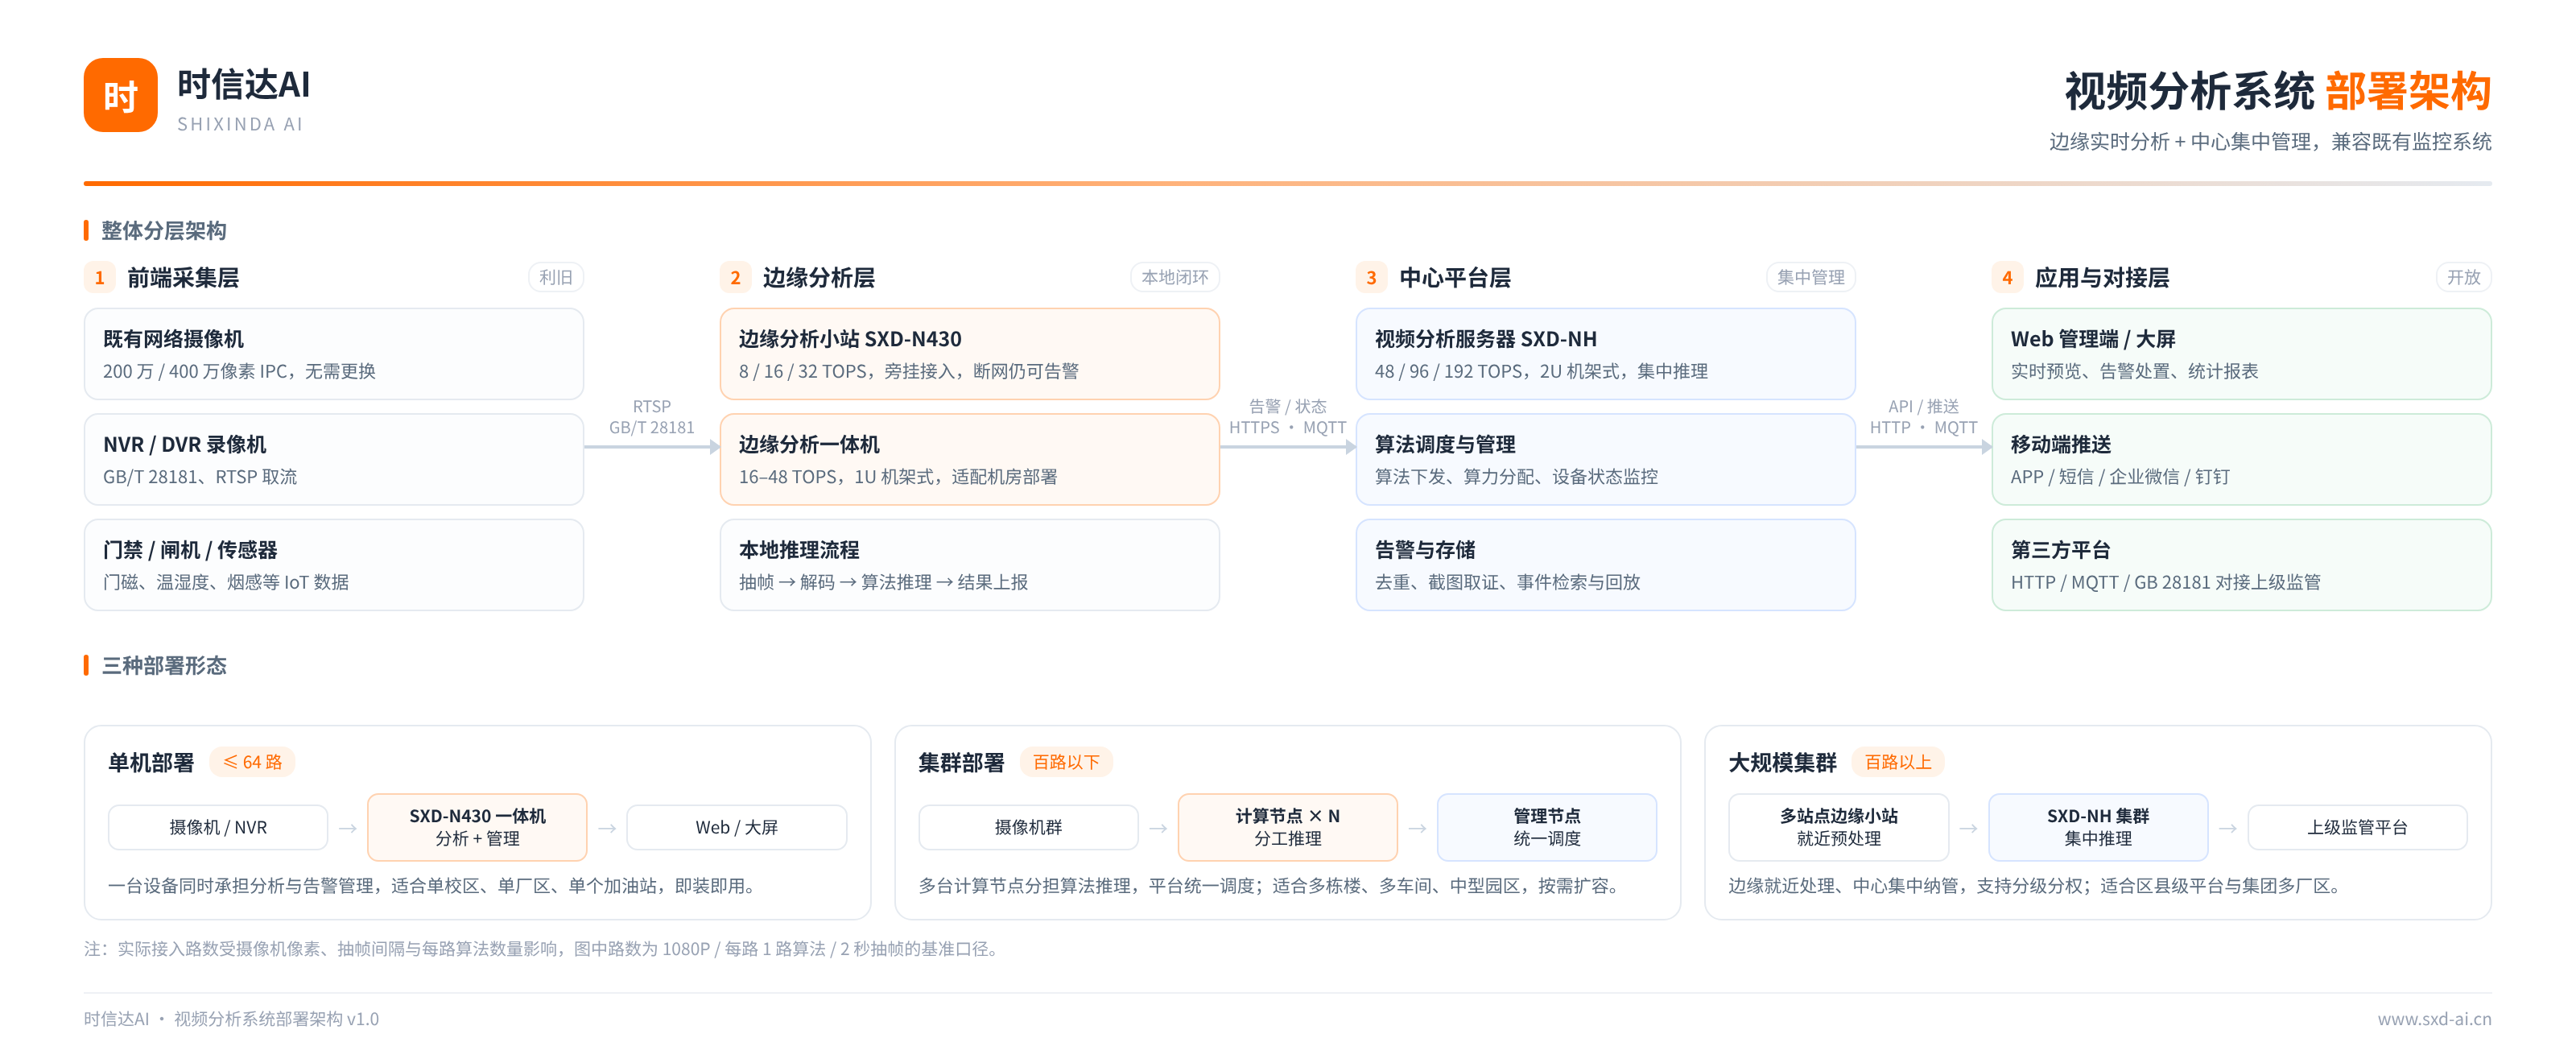
Deployment Architecture
Core Features
- 48 TOPS compute: Up to 192 concurrent algorithm channels across the full stream, with up to 24 algorithms per channel
- 128-channel decoding: One device covers the main locations of a large campus
- Four network ports: Multi-subnet access, suitable for video private network/office network isolation
- Local 4TB storage: Alarm images stored for approximately 3 months
Typical Applications
Large industrial parks, city-level monitoring centers, multi-campus schools, large factories.
Related Recommendations
- Solution: Smart Campus Security Monitoring Upgrade Solution
- Solution: Smart Classroom Behavior Analytics Solution
References
The following are regulations and standards related to this document for further verification:
- "Technical Requirements for Information Transmission, Exchange, and Control of Public Security Video Surveillance Networked Systems" (GB/T 28181) — Official Source
- "Data Security Law of the People's Republic of China" — Official Source
Applications
Core Features
48 TOPS@INT8 / 12 TOPS@INT16 / 384 GFLOPS FP32
3×24 核 ARM@1.6GHz(内置 AI 加速引擎)
系统 24GB + AI 24GB
4TB SSD(告警图片约存 3 个月)
Specifications
| Item | Specification |
|---|---|
| Model | SXD-N430UW (1U rack-mount) |
| AI Computing Power | 48 TOPS@INT8 / 12 TOPS@INT16 / 384 GFLOPS FP32 |
| Processor | 3× 24-core ARM@1.6GHz (built-in AI acceleration engine) |
| Memory | System 24GB + AI 24GB |
| Storage | 4TB SSD (stores approximately 3 months of alarm images) |
Expand all(17)
| Video Decoding | 128 channels 1080P@25fps |
|---|---|
| Video Encoding | 24 channels 1080P@25fps |
| Algorithm Capability | Up to 24 algorithms per channel; maximum 192 parallel across all video streams |
| Face Database | Supports enrollment of 10,000 faces |
| Interfaces | Gigabit Ethernet ports ×4, USB3.0 ×3, HDMI ×1, Audio ×1, RS232 ×1, RS485 ×1, DebugUart ×1 |
| Power Supply | 180W, 100–240V AC |
| Power Consumption | 120W (MAX) |
| Dimensions | 440×450×44mm (482.6mm wide including mounting ears) |
| Weight | 7.20kg |
| Operating Environment | 0℃~45℃, humidity 20%~80%RH non-condensing |
| Operating System | openEuler (domestic) |
Downloads
FAQ
How many cameras can 48 TOPS actually support?
The stated 128 channels is the baseline specification (1080P/25fps/1 algorithm per channel/2-second frame sampling). If you switch to 4-megapixel cameras, estimate around 70 channels; if you change to 1-second frame sampling, the number of supported channels is roughly halved; adding one more algorithm per channel halves it again.
What is the difference in compute load between a 2-megapixel and a 4-megapixel camera?
The data volume per frame for a 4-megapixel camera is about twice that of a 2-megapixel camera, so decoding and inference loads increase accordingly. With the same compute capacity, plan for a 4-megapixel deployment at 50%–60% of the number of streams a 2-megapixel camera can support, and reserve headroom for peak loads.
How should I choose between 1-second and 2-second frame extraction?
For alarm-type scenarios (line crossing, fighting, smoke/fire, absence from post), 1-second extraction is recommended—it gives faster response but doubles compute usage. For statistics-type scenarios (foot traffic, counting, on-duty duration), 2 seconds is sufficient and allows more camera streams. In mixed scenarios, you can set 1-second extraction separately for key locations.
Which algorithms does the device support?
They are grouped into six major categories by scenario: personnel behavior and on-duty presence, safety risks and fire prevention, vehicles and traffic, objects and facilities, environment and order, and food and kitchen operations, covering over 460 sub-scenarios. Which specific algorithms are enabled depends on the project configuration, and a list will be provided at delivery; algorithms involving facial images must be used within the authorized scope.
Can we train the algorithm using our own on-site data?
Yes. The accompanying AI algorithm training platform supports four stages: data annotation, model training, model evaluation, and model release. You can import on-site images (either locally or via data回流), perform manual or intelligent annotation, select segmentation/detection/classification models for training, and after evaluation passes, quantize and generate an SG file to deploy to the device. The training platform requires a GPU server, which is optional per project.
With the same 8 TOPS, why can you handle more channels?
Because the nominal TOPS is only a peak upper limit; actual performance = peak × chip utilization. Common instruction-set architectures (GPU/NPU) achieve about 10%–30% utilization, while a reconfigurable dataflow architecture can reach 65%–95%. With the same 8 TOPS, the effective compute of a dataflow solution is about 5.2–7.6 TOPS, so it can naturally handle more channels; the exact number of channels is also affected by camera resolution, frame-sampling interval, and the number of algorithms per channel.
Related Products
View All →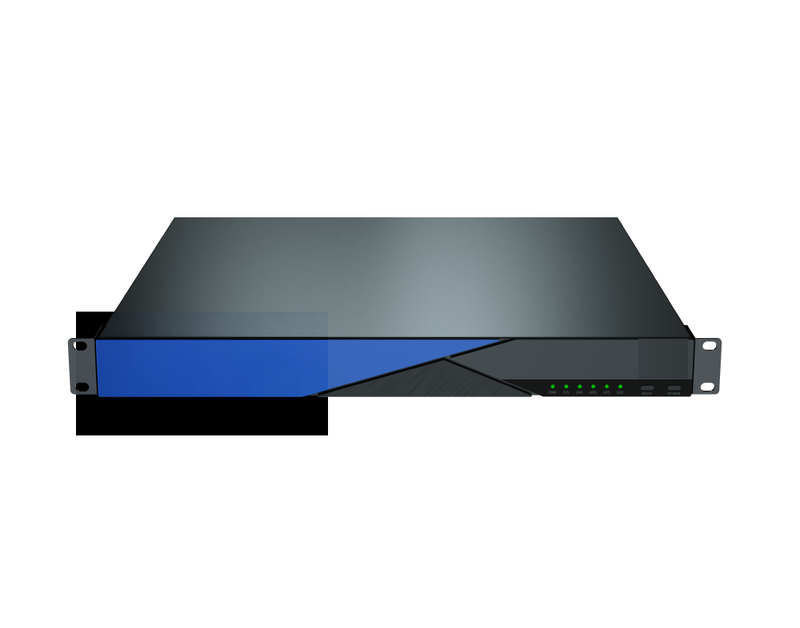
Shixinda AI AI Video Analytics Edge All-in-One Device (16-48 TOPS)
48 TOPSLegacy Cameras + Shixinda AI Brain: Standard 1U rack-mount design, it can retrofit AI capabilities to the entire existing surveillance system simply by replacin…
Learn More →Shixinda AI SXD-N430PW Edge Analytics All-in-One
32 TOPSShixinda AI Integrated Edge AI Analytics Device, integrating video input, intelligent analytics, and local storage, delivers a peak computing power of 32 TOPS a…
Learn More →SXD-N430SW Edge Analytics Appliance
16 TOPSSXD-N430SW Edge Analytics Appliance is a 16 TOPS edge AI analytics device, rated to support 32 channels of real-time video input (1080P, 1 algorithm per channel, 2-second frame sampling basis); the number of supported channels varies with camera pixel resolution, frame sampling interval, and the number of algorithms per channel. Selection must be calculated based on the actual scenario with a 30% margin reserved.
Learn More →SXD-N430 Series Edge Analytics All-in-One Appliance
SXD-N430 Series Edge Analytics Appliance, 1U rack-mount, 16–32 TOPS tiered options, selectable by camera count scale, suitable for centralized data center deployment and nearby analytics.
Learn More →← PrevSXD-N430SW Edge Analytics Appliance (16 TOPS)Next →SXD-N430 Series Edge Analytics All-in-One ApplianceReady to go smart?
Leave a message or call us for tailored selection advice.